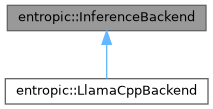
Concrete base class for inference backends (80% logic). More...
#include <entropic/inference/backend.h>
Public Member Functions | |
| bool | load (const ModelConfig &config) |
| Load model into CPU RAM (COLD → WARM). | |
| bool | activate () |
| Promote to GPU (WARM → ACTIVE). | |
| void | deactivate () |
| Release GPU layers (ACTIVE → WARM). | |
| void | unload () |
| Full unload (→ COLD). | |
| bool | load_and_activate (const ModelConfig &config) |
| Bring a model to ACTIVE in as few file reads as possible. | |
| GenerationResult | generate (const std::vector< Message > &messages, const GenerationParams ¶ms) |
| Generate a complete response. | |
| GenerationResult | generate (const std::vector< Message > &messages, const GenerationParams ¶ms, std::atomic< bool > &cancel) |
| Generate a complete response with cancellation support. | |
| GenerationResult | generate_streaming (const std::vector< Message > &messages, const GenerationParams ¶ms, std::function< void(std::string_view token)> on_token, std::atomic< bool > &cancel) |
| Generate with per-token streaming callback. | |
| GenerationResult | generate_speculative (const std::vector< Message > &messages, const GenerationParams ¶ms, std::function< void(std::string_view token)> on_token, std::atomic< bool > &cancel) |
| Generate via the speculative-decoding kernel (v2.1.11). | |
| GenerationResult | complete (const std::string &prompt, const GenerationParams ¶ms) |
| Raw text completion without chat template. | |
| LogprobResult | evaluate_logprobs (const int32_t *tokens, int n_tokens) |
| Evaluate per-token log-probabilities for a token sequence. | |
| float | compute_perplexity (const int32_t *tokens, int n_tokens) |
| Compute perplexity for a token sequence. | |
| ModelState | state () const |
| Current lifecycle state (lock-free read). | |
| bool | is_active () const |
| True when state is ACTIVE. | |
| bool | is_loaded () const |
| True when state is WARM or ACTIVE. | |
| int | count_tokens (const std::string &text) const |
| Count tokens using model's tokenizer. | |
| virtual std::vector< int32_t > | tokenize_text (const std::string &text) const |
| Tokenize text to token IDs. | |
| int | context_length () const |
| Model's context window size. | |
| virtual void | clear_prompt_cache () |
| Invalidate any backend-owned prompt/KV caches. | |
| virtual std::string | tool_call_close_marker () const |
| The tool-call CLOSE marker for the active chat format (gh#103). | |
| const ModelConfig & | config () const |
| Stored model config. | |
| bool | supports (BackendCapability cap) const |
| Query whether this backend supports a capability. | |
| std::vector< BackendCapability > | capabilities () const |
| Get all supported capabilities as a vector. | |
| BackendInfo | info () const |
| Get backend metadata. | |
| virtual std::string | active_tool_grammar () const |
| The tool-call GBNF the last render derived, if any (gh#154). | |
| bool | save_state (int seq_id, std::vector< uint8_t > &buffer) const |
| Save model state to buffer. | |
| bool | restore_state (int seq_id, const std::vector< uint8_t > &buffer) |
| Restore model state from buffer. | |
| bool | clear_state (int seq_id=-1) |
| Clear/reset model state for a sequence. | |
| GenerationResult | generate_seq (int seq_id, const std::vector< Message > &messages, const GenerationParams ¶ms) |
| Generate with explicit sequence ID. | |
| GenerationResult | generate_streaming_seq (int seq_id, const std::vector< Message > &messages, const GenerationParams ¶ms, std::function< void(std::string_view token)> on_token, std::atomic< bool > &cancel) |
| Streaming generation with explicit sequence ID. | |
| std::vector< GenerationResult > | generate_batch (const std::vector< std::vector< Message > > &requests, const std::vector< GenerationParams > ¶ms, std::atomic< bool > &cancel) |
| Generate N independent same-prefix requests together. | |
| virtual void | forget_session_kv (const std::string &session_key) |
| Drop one session's resident KV and release its slot (gh#165). | |
Protected Member Functions | |
| virtual bool | do_load (const ModelConfig &config)=0 |
| Load model into CPU RAM. | |
| virtual bool | do_activate ()=0 |
| Promote loaded model to GPU. | |
| virtual bool | do_load_active (const ModelConfig &config) |
| Load COLD → ACTIVE in one step. | |
| virtual void | do_deactivate ()=0 |
| Release GPU, keep CPU. | |
| virtual void | do_unload ()=0 |
| Full unload. | |
| virtual GenerationResult | do_generate (const std::vector< Message > &messages, const GenerationParams ¶ms)=0 |
| Subclass generation. | |
| virtual GenerationResult | do_generate (const std::vector< Message > &messages, const GenerationParams ¶ms, std::atomic< bool > &cancel) |
| Subclass batch generation with cancel-flag support. | |
| virtual std::vector< GenerationResult > | do_generate_batch (const std::vector< std::vector< Message > > &requests, const std::vector< GenerationParams > ¶ms, std::atomic< bool > &cancel) |
| Subclass same-prefix batch generation (gh#98, v2.8.0). | |
| virtual GenerationResult | do_generate_streaming (const std::vector< Message > &messages, const GenerationParams ¶ms, std::function< void(std::string_view token)> on_token, std::atomic< bool > &cancel)=0 |
| Subclass streaming generation. | |
| virtual GenerationResult | do_generate_speculative (const std::vector< Message > &messages, const GenerationParams ¶ms, std::function< void(std::string_view token)> on_token, std::atomic< bool > &cancel) |
| Subclass speculative-decoding streaming generation. | |
| virtual GenerationResult | do_complete (const std::string &prompt, const GenerationParams ¶ms)=0 |
| Subclass raw completion. | |
| virtual int | do_count_tokens (const std::string &text) const =0 |
| Subclass token counting. | |
| virtual LogprobResult | do_evaluate_logprobs (const int32_t *tokens, int n_tokens)=0 |
| Backend-specific logprob evaluation. | |
| virtual bool | do_supports (BackendCapability cap) const |
| Declare supported capabilities. | |
| virtual std::string | do_backend_name () const =0 |
| Return backend name identifier. | |
| virtual BackendInfo | do_info () const |
| Populate backend metadata. | |
| virtual bool | do_save_state (int seq_id, std::vector< uint8_t > &buffer) const |
| Save model state (KV cache or hidden state). | |
| virtual bool | do_restore_state (int seq_id, const std::vector< uint8_t > &buffer) |
| Restore model state. | |
| virtual bool | do_clear_state (int seq_id) |
| Clear/reset model state. | |
| virtual GenerationResult | do_generate_seq (int seq_id, const std::vector< Message > &messages, const GenerationParams ¶ms) |
| Generate with sequence ID. | |
| virtual GenerationResult | do_generate_streaming_seq (int seq_id, const std::vector< Message > &messages, const GenerationParams ¶ms, std::function< void(std::string_view token)> on_token, std::atomic< bool > &cancel) |
| Streaming generation with sequence ID. | |
| bool | fire_model_load_hook (const ModelConfig &config) |
| Fire ON_MODEL_LOAD pre-hook. | |
| bool | promote_to_active () |
| WARM → ACTIVE promotion. | |
| void | set_hooks (const HookInterface &hooks) |
| Set the hook dispatch interface. | |
Protected Attributes | |
| std::string | last_error_ |
| Last error message for diagnostics. | |
| std::atomic< ModelState > | state_ {ModelState::COLD} |
| State transition slot accessible to subclasses for test-only injection. | |
Detailed Description
Concrete base class for inference backends (80% logic).
Public methods implement the lifecycle state machine, transition locking, timing, and logging. Protected virtual methods are the 20% that subclasses override with backend-specific logic.
- Transition rules (enforced by base class)
- load(): COLD → WARM (no-op if WARM/ACTIVE)
- activate(): WARM → ACTIVE (auto-loads if COLD)
- deactivate(): ACTIVE → WARM (no-op if not ACTIVE)
- unload(): any → COLD (idempotent)
- load_and_activate(): COLD → ACTIVE (convenience)
Invalid transitions are no-ops with INFO log (not errors).
- Version
- 1.9.13
Member Function Documentation
◆ activate()
| bool entropic::InferenceBackend::activate | ( | ) |
Promote to GPU (WARM → ACTIVE).
Loads first if COLD.
- Returns
- true on success.
- Version
- 1.8.2
- Returns
- true on success, false on failure. @dg_internal
- Version
- 2.13.0
Definition at line 88 of file backend.cpp.
◆ active_tool_grammar()
|
inlinevirtual |
The tool-call GBNF the last render derived, if any (gh#154).
The second grammar source (the first being GenerationParams::grammar). It never appears on the params, so a caller holding only the params cannot tell whether the decode was constrained — the orchestrator asks the backend instead, and builds GenerationResult::grammar from both.
Base returns "" — a backend that stages no tools has no such grammar, which is the honest answer rather than a stub.
- Returns
- Render-derived tool-call GBNF, or "" when none is staged. @req REQ-INFER-008
- Version
- 2.13.0
Reimplemented in entropic::LlamaCppBackend.
◆ capabilities()
| std::vector< BackendCapability > entropic::InferenceBackend::capabilities | ( | ) | const |
Get all supported capabilities as a vector.
Get all supported capabilities.
- Returns
- Vector of capabilities this backend supports.
Convenience method. Iterates BackendCapability enum, calls supports() on each.
- Version
- 1.9.13
Iteration is bounded by the _COUNT sentinel rather than a hardcoded length, so a capability appended to the enum is enumerated here without a second edit — the sentinel is what makes the sweep exhaustive.
- Returns
- Vector of every capability index below
_COUNTfor which supports() is true; the sentinel is never included. @req REQ-TYPE-004
- Version
- 1.9.13
Definition at line 591 of file backend.cpp.
◆ clear_prompt_cache()
Invalidate any backend-owned prompt/KV caches.
Called when identity or prompt-prefix inputs change so stale cached prefixes are never served against the new system prompt. Default is a no-op for backends with no cache. (P1-7, 2.0.6-rc16)
@utility
- Version
- 2.0.6-rc16
Reimplemented in entropic::LlamaCppBackend.
◆ clear_state()
Clear/reset model state for a sequence.
Clear model state.
- Parameters
-
seq_id Sequence identifier (-1 for all sequences).
- Returns
- true on success.
For transformers: clears KV cache. For recurrent: resets hidden state to initial values.
- Version
- 1.9.13
Requires WARM or ACTIVE.
- Parameters
-
seq_id Sequence ID, or -1 to clear every sequence.
- Returns
- true on success; false when the model is COLD or the backend does not support the operation. @req REQ-INFER-024
- Version
- 1.9.13
Definition at line 675 of file backend.cpp.
◆ complete()
| GenerationResult entropic::InferenceBackend::complete | ( | const std::string & | prompt, |
| const GenerationParams & | params | ||
| ) |
Raw text completion without chat template.
Raw text completion.
- Parameters
-
prompt Raw prompt string (no chat formatting). params Generation parameters.
- Returns
- GenerationResult.
- Version
- 1.8.2
Requires ACTIVE state.
- Parameters
-
prompt Raw prompt string. params Generation parameters.
- Returns
- GenerationResult. @dg_internal
- Version
- 2.0.0
Definition at line 422 of file backend.cpp.
◆ compute_perplexity()
Compute perplexity for a token sequence.
- Parameters
-
tokens Array of token IDs. n_tokens Number of tokens (minimum 2).
- Returns
- Perplexity as exp(-mean(logprobs)).
Convenience method — calls evaluate_logprobs() and returns only the perplexity value.
- Version
- 1.9.10
Convenience wrapper — calls evaluate_logprobs() and returns only the perplexity value.
- Parameters
-
tokens Array of token IDs. n_tokens Number of tokens (minimum 2).
- Returns
- Perplexity as exp(-mean(logprobs)). @dg_internal
- Version
- 1.9.10
Definition at line 517 of file backend.cpp.
◆ config()
|
inline |
Stored model config.
- Returns
- Const reference to the ModelConfig used for this backend. @utility
- Version
- 1.8.2
◆ context_length()
|
inline |
◆ count_tokens()
Count tokens using model's tokenizer.
Count tokens.
- Returns
- Exact count if loaded, len/4 estimate if COLD.
- Version
- 1.8.2
Exact if loaded, estimate if COLD.
- Parameters
-
text Text to tokenize.
- Returns
- Token count. @dg_internal
- Version
- 1.8.2
Definition at line 558 of file backend.cpp.
◆ deactivate()
| void entropic::InferenceBackend::deactivate | ( | ) |
Release GPU layers (ACTIVE → WARM).
No-op if not ACTIVE.
- Version
- 1.8.2
No-op if not ACTIVE. @dg_internal
- Version
- 2.0.0
Definition at line 132 of file backend.cpp.
◆ do_activate()
Promote loaded model to GPU.
Called under transition_mutex_.
- Version
- 1.8.2
Implemented in entropic::LlamaCppBackend.
◆ do_backend_name()
|
protectedpure virtual |
Return backend name identifier.
- Returns
- Short name (e.g. "llama.cpp", "axcl").
Pure virtual — every backend must identify itself.
- Version
- 1.9.13
Implemented in entropic::LlamaCppBackend.
◆ do_clear_state()
Clear/reset model state.
Default: state clear not supported.
- Parameters
-
seq_id Sequence ID, or -1 for all.
- Returns
- true on success. Default: returns false (not supported).
- Version
- 1.9.13
- Parameters
-
seq_id Sequence identifier.
- Returns
- false. @dg_internal
- Version
- 1.9.13
Reimplemented in entropic::LlamaCppBackend.
Definition at line 815 of file backend.cpp.
◆ do_complete()
|
protectedpure virtual |
Subclass raw completion.
Called only when ACTIVE.
- Parameters
-
prompt Raw prompt string (no chat template applied). params Generation parameters.
- Returns
- Generation result populated by the subclass.
- Version
- 1.8.2
Implemented in entropic::LlamaCppBackend.
◆ do_count_tokens()
|
protectedpure virtual |
Subclass token counting.
Called only when model loaded.
- Parameters
-
text Text whose tokens should be counted.
- Returns
- Token count for the provided text.
- Version
- 1.8.2
Implemented in entropic::LlamaCppBackend.
◆ do_deactivate()
Release GPU, keep CPU.
Called under transition_mutex_.
- Version
- 1.8.2
Implemented in entropic::LlamaCppBackend.
◆ do_evaluate_logprobs()
|
protectedpure virtual |
Backend-specific logprob evaluation.
- Parameters
-
tokens Token IDs to evaluate. n_tokens Number of tokens.
- Returns
- LogprobResult with per-token logprobs (N-1 values).
Called by evaluate_logprobs() after state validation and eval_mutex_ acquisition. The base class handles state assertion, minimum token count validation, mutex, perplexity computation from logprobs, and logging. The implementation handles batch allocation, decode calls, logit extraction, and temporary seq_id lifecycle.
- Version
- 1.9.10
Implemented in entropic::LlamaCppBackend.
◆ do_generate() [1/2]
|
protectedpure virtual |
Subclass generation.
Called only when ACTIVE.
- Parameters
-
messages Conversation history. params Generation parameters.
- Returns
- Generation result populated by the subclass.
- Version
- 1.8.2
Implemented in entropic::LlamaCppBackend.
◆ do_generate() [2/2]
|
inlineprotectedvirtual |
Subclass batch generation with cancel-flag support.
gh#81 (v2.4.2): default implementation ignores cancel and delegates to the no-cancel do_generate override, preserving pre-v2.4.2 behavior for backends that haven't opted in. Backends that want responsive interrupts override this method and poll cancel per decode iteration (mirroring do_generate_streaming).
- Parameters
-
messages Conversation history. params Generation parameters. cancel Atomic cancel flag; ignored by this default.
- Returns
- Generation result from the no-cancel
do_generateoverride — behaviourally identical to not passing a flag at all. @req REQ-INFER-005
- Version
- 2.4.2
Reimplemented in entropic::LlamaCppBackend.
◆ do_generate_batch()
|
inlineprotectedvirtual |
Subclass same-prefix batch generation (gh#98, v2.8.0).
Default implementation is a transparent serial fallback: each request runs through the single-request do_generate in turn. Backends that support multi-sequence batched decode (LlamaCppBackend on a plain-KV arch) override this to prefill the shared prefix once and fan out.
- Parameters
-
requests Per-request message lists. params Per-request generation params. cancel Atomic cancel flag.
- Returns
- One result per request, in input order. @dg_internal
- Version
- 2.8.0
Reimplemented in entropic::LlamaCppBackend.
◆ do_generate_seq()
|
protectedvirtual |
Generate with sequence ID.
Default: ignores seq_id, delegates to do_generate().
- Parameters
-
seq_id Sequence identifier. messages Conversation history. params Generation parameters.
- Returns
- GenerationResult.
Default: ignores seq_id, delegates to do_generate().
- Version
- 1.9.13
- Parameters
-
seq_id Sequence identifier (ignored). messages Conversation history. params Generation parameters.
- Returns
- GenerationResult from do_generate(). @dg_internal
- Version
- 1.9.13
Definition at line 828 of file backend.cpp.
◆ do_generate_speculative()
|
protectedvirtual |
Subclass speculative-decoding streaming generation.
Default implementation of speculative streaming generation.
Same contract as do_generate_streaming (callback fires once per accepted token, cancel flag honored between accept rounds) but the backend is expected to drive a draft model through common_speculative_* (or equivalent) to propose tokens, then verify them in batch against the target. Output distribution MUST be bit-identical to plain decode on rejection cases (correctness contract from the v2.1.11 proposal).
Default returns a result with ENTROPIC_ERROR_NOT_SUPPORTED — backends that don't implement speculative fall through to the standard streaming path via the orchestrator.
- Parameters
-
messages Conversation history. params Generation parameters. on_token Callback for each accepted token. cancel Atomic cancel flag.
- Returns
- Generation result. On NOT_SUPPORTED, caller should fall back to do_generate_streaming.
- Version
- 2.1.11
Returns ENTROPIC_ERROR_NOT_SUPPORTED so the orchestrator falls back to plain do_generate_streaming. Backends that implement the speculative kernel override this method. (v2.1.11, gh#36)
- Parameters
-
messages Unused in default impl. params Unused in default impl. on_token Unused in default impl. cancel Unused in default impl.
- Returns
- GenerationResult with NOT_SUPPORTED error code. @dg_internal
- Version
- 2.1.11
Reimplemented in entropic::LlamaCppBackend.
Definition at line 400 of file backend.cpp.
◆ do_generate_streaming()
|
protectedpure virtual |
Subclass streaming generation.
Called only when ACTIVE.
- Parameters
-
messages Conversation history. params Generation parameters. on_token Callback invoked per emitted token. cancel Atomic flag — when true, subclass must stop streaming.
- Returns
- Generation result populated by the subclass.
- Version
- 1.8.2
Implemented in entropic::LlamaCppBackend.
◆ do_generate_streaming_seq()
|
protectedvirtual |
Streaming generation with sequence ID.
Default: ignores seq_id, delegates to do_generate_streaming().
- Parameters
-
seq_id Sequence identifier. messages Conversation history. params Generation parameters. on_token Per-token callback. cancel Cancellation flag.
- Returns
- GenerationResult.
Default: ignores seq_id, delegates to do_generate_streaming().
- Version
- 1.9.13
- Parameters
-
seq_id Sequence identifier (ignored). messages Conversation history. params Generation parameters. on_token Per-token callback. cancel Cancellation flag.
- Returns
- GenerationResult from do_generate_streaming(). @dg_internal
- Version
- 1.9.13
Definition at line 847 of file backend.cpp.
◆ do_info()
|
protectedvirtual |
Populate backend metadata.
Default: BackendInfo with name only.
- Returns
- BackendInfo with model-specific details.
Default: returns BackendInfo with name from do_backend_name().
- Version
- 1.9.13
- Returns
- BackendInfo with name from do_backend_name(). @dg_internal
- Version
- 1.9.13
Reimplemented in entropic::LlamaCppBackend.
Definition at line 774 of file backend.cpp.
◆ do_load()
|
protectedpure virtual |
Load model into CPU RAM.
Called under transition_mutex_.
- Parameters
-
config Validated model config.
- Returns
- true on success. Set last_error_ on failure.
- Version
- 1.8.2
Implemented in entropic::LlamaCppBackend.
◆ do_load_active()
|
inlineprotectedvirtual |
Load COLD → ACTIVE in one step.
Called under transition_mutex_.
The default is the historical behaviour — load, then activate — so a subclass that has no cheaper route (and every mock) keeps working unchanged. LlamaCppBackend overrides it to read the file ONCE with the configured gpu_layers instead of reading it once for the CPU placement and again for the real one (gh#148).
- Parameters
-
config Validated model config.
- Returns
- true on success. Set last_error_ on failure. @req REQ-INFER-002
- Version
- 2.13.0
Reimplemented in entropic::LlamaCppBackend.
◆ do_restore_state()
|
protectedvirtual |
Restore model state.
Default: state restore not supported.
- Parameters
-
seq_id Sequence identifier. buffer State data to restore.
- Returns
- true on success. Default: returns false (not supported).
- Version
- 1.9.13
- Parameters
-
seq_id Sequence identifier. buffer State data.
- Returns
- false. @dg_internal
- Version
- 1.9.13
Reimplemented in entropic::LlamaCppBackend.
Definition at line 802 of file backend.cpp.
◆ do_save_state()
|
protectedvirtual |
Save model state (KV cache or hidden state).
Default: state save not supported.
- Parameters
-
seq_id Sequence identifier. buffer Output buffer.
- Returns
- true on success. Default: returns false (not supported).
- Version
- 1.9.13
- Parameters
-
seq_id Sequence identifier. buffer Output buffer.
- Returns
- false. @dg_internal
- Version
- 1.9.13
Reimplemented in entropic::LlamaCppBackend.
Definition at line 788 of file backend.cpp.
◆ do_supports()
|
protectedvirtual |
Declare supported capabilities.
Default: no capabilities supported.
- Parameters
-
cap Capability to check.
- Returns
- true if this backend supports the capability.
Default: returns false for everything.
- Version
- 1.9.13
- Parameters
-
cap Capability to check.
- Returns
- false. @dg_internal
- Version
- 1.9.13
Reimplemented in entropic::LlamaCppBackend.
Definition at line 764 of file backend.cpp.
◆ do_unload()
◆ evaluate_logprobs()
| LogprobResult entropic::InferenceBackend::evaluate_logprobs | ( | const int32_t * | tokens, |
| int | n_tokens | ||
| ) |
Evaluate per-token log-probabilities for a token sequence.
Evaluate per-token log-probabilities.
- Parameters
-
tokens Array of token IDs to evaluate. n_tokens Number of tokens in the array (minimum 2).
- Returns
- LogprobResult with per-token logprobs and perplexity.
- Exceptions
-
std::runtime_error if model is not ACTIVE. std::runtime_error if n_tokens < 2.
- Thread safety
- Serialized by eval_mutex_. Does not block generation. Uses a temporary KV cache sequence ID — no mutation of generation state.
- Version
- 1.9.10
Requires ACTIVE state.
The 80% logic: state check, input validation, eval_mutex_, perplexity computation from raw logprobs, and logging. Delegates to do_evaluate_logprobs() for backend-specific batch/decode work.
- Parameters
-
tokens Array of token IDs. n_tokens Number of tokens (minimum 2).
- Exceptions
-
std::runtime_error on state/input errors.
- Returns
- LogprobResult whose perplexity equals exp(-mean(logprobs)) and total_logprob the sum; deterministic across repeated calls. Rejected for fewer than 2 tokens or a non-ACTIVE model. @req REQ-INFER-024
- Version
- 2.0.0
Definition at line 459 of file backend.cpp.
◆ fire_model_load_hook()
|
protected |
Fire ON_MODEL_LOAD pre-hook.
- Parameters
-
config Model config being loaded.
- Returns
- true if hook cancelled the load.
- Version
- 1.9.1 @dg_internal
- Parameters
-
config Model config being loaded.
- Returns
- true if hook cancelled the load. @dg_internal
- Version
- 1.9.1
Definition at line 533 of file backend.cpp.
◆ forget_session_kv()
|
inlinevirtual |
Drop one session's resident KV and release its slot (gh#165).
Called when a session's conversation is REPLACED wholesale (entropic_session_context_set), so the restored history cannot decode against a prefix the conversation it replaced left in the cache. The session's next turn costs a cold prefill, which is exactly what an LRU-evicted session already costs.
Default is a no-op: a backend with no per-session KV has nothing to forget, and every mock therefore needs no override (decision #32 — new methods carry a default implementation).
- Parameters
-
session_key Session whose KV to drop; ""is the default session. @req REQ-LOOP-010
- Version
- 2.13.0
Reimplemented in entropic::LlamaCppBackend.
◆ generate() [1/2]
| GenerationResult entropic::InferenceBackend::generate | ( | const std::vector< Message > & | messages, |
| const GenerationParams & | params | ||
| ) |
Generate a complete response.
- Parameters
-
messages Conversation history. params Generation parameters.
- Returns
- GenerationResult with content, token count, timing. Returns error result if not ACTIVE.
- Version
- 1.8.2
Requires ACTIVE state.
- Parameters
-
messages Conversation history. params Generation parameters.
- Returns
- GenerationResult (error result if not ACTIVE). @dg_internal
- Version
- 2.0.0
Definition at line 234 of file backend.cpp.
◆ generate() [2/2]
| GenerationResult entropic::InferenceBackend::generate | ( | const std::vector< Message > & | messages, |
| const GenerationParams & | params, | ||
| std::atomic< bool > & | cancel | ||
| ) |
Generate a complete response with cancellation support.
Generate with cancel support.
gh#81 (v2.4.2): the no-cancel generate overload above runs to max_tokens or natural stop with no path to honor a mid-decode interrupt. The engine's loop-top interrupt check can then take a full generation cycle to fire — observed ~60s on qwen3_6_a3b at max_tokens=400.
This overload mirrors generate_streaming's contract: the backend polls cancel per token (latency: one token) and returns a result with finish_reason="cancelled" and error_code=ENTROPIC_ERROR_CANCELLED when cancellation lands.
- Parameters
-
messages Conversation history. params Generation parameters. cancel Atomic flag — when true, subclass must stop decoding.
- Returns
- GenerationResult.
- Version
- 2.4.2
Requires ACTIVE state. (gh#81, v2.4.2)
- Parameters
-
messages Conversation history. params Generation parameters. cancel Atomic cancel flag forwarded to the subclass decode loop.
- Returns
- GenerationResult with generation_time_ms stamped; an ENTROPIC_ERROR_INVALID_STATE result when the backend is not ACTIVE. @req REQ-INFER-005
- Version
- 2.4.2
Definition at line 264 of file backend.cpp.
◆ generate_batch()
| std::vector< GenerationResult > entropic::InferenceBackend::generate_batch | ( | const std::vector< std::vector< Message > > & | requests, |
| const std::vector< GenerationParams > & | params, | ||
| std::atomic< bool > & | cancel | ||
| ) |
Generate N independent same-prefix requests together.
Same-prefix batch generation.
For traffic where N requests share a large verbatim prompt prefix and differ only in a short suffix (e.g. NPC agents per game tick): the shared prefix is prefilled once and fanned out to N sequences, then the suffixes + outputs are decoded in batched forward passes, each sampled under its own request's grammar. Requires ACTIVE state.
- Parameters
-
requests Per-request message lists (all sharing a prefix). params Per-request generation params (each may carry its grammar). cancel Cooperative cancel flag.
- Returns
- One GenerationResult per request, in input order.
- Version
- 2.8.0
Requires ACTIVE state. (gh#98, v2.8.0)
- Parameters
-
requests Per-request message lists. params Per-request generation params. cancel Atomic cancel flag forwarded to the batch decode loop.
- Returns
- One result per request (single error result if not ACTIVE). @req REQ-INFER-005
- Version
- 2.8.0
Definition at line 293 of file backend.cpp.
◆ generate_seq()
| GenerationResult entropic::InferenceBackend::generate_seq | ( | int | seq_id, |
| const std::vector< Message > & | messages, | ||
| const GenerationParams & | params | ||
| ) |
Generate with explicit sequence ID.
- Parameters
-
seq_id Sequence identifier for multi-sequence backends. messages Conversation history. params Generation parameters.
- Returns
- GenerationResult with seq_id set.
Default: ignores seq_id, delegates to generate().
- Version
- 1.9.13
Requires ACTIVE.
- Parameters
-
seq_id Sequence identifier. messages Conversation history. params Generation parameters.
- Returns
- GenerationResult with seq_id set. @dg_internal
- Version
- 2.0.0
Definition at line 698 of file backend.cpp.
◆ generate_speculative()
| GenerationResult entropic::InferenceBackend::generate_speculative | ( | const std::vector< Message > & | messages, |
| const GenerationParams & | params, | ||
| std::function< void(std::string_view token)> | on_token, | ||
| std::atomic< bool > & | cancel | ||
| ) |
Generate via the speculative-decoding kernel (v2.1.11).
Public entry point for speculative-decoding streaming.
Public wrapper around do_generate_speculative. Validates ACTIVE state, then delegates to the subclass override. Backends that do not implement the kernel return ENTROPIC_ERROR_NOT_SUPPORTED — the orchestrator falls back to generate_streaming in that case.
- Parameters
-
messages Conversation history. params Generation parameters. on_token Per-accepted-token callback. cancel Cancellation flag.
- Returns
- GenerationResult.
- Version
- 2.1.11
Mirrors generate_streaming: validates ACTIVE state then delegates to the subclass override. Stamps generation_time_ms. Returns the subclass's NOT_SUPPORTED on stub backends — caller falls back to generate_streaming.
- Parameters
-
messages Conversation history. params Generation parameters. on_token Per-accepted-token callback. cancel Cancellation flag.
- Returns
- GenerationResult. @dg_internal
- Version
- 2.1.11
Definition at line 362 of file backend.cpp.
◆ generate_streaming()
| GenerationResult entropic::InferenceBackend::generate_streaming | ( | const std::vector< Message > & | messages, |
| const GenerationParams & | params, | ||
| std::function< void(std::string_view token)> | on_token, | ||
| std::atomic< bool > & | cancel | ||
| ) |
Generate with per-token streaming callback.
Streaming generation.
- Parameters
-
messages Conversation history. params Generation parameters. on_token Called for each token (valid only during callback). cancel Set to true to abort. Latency: one token.
- Returns
- GenerationResult with final content and timing.
- Version
- 1.8.2
Requires ACTIVE state.
- Parameters
-
messages Conversation history. params Generation parameters. on_token Per-token callback. cancel Atomic cancel flag forwarded to the subclass decode loop.
- Returns
- GenerationResult with generation_time_ms stamped; an ENTROPIC_ERROR_INVALID_STATE result when the backend is not ACTIVE. @req REQ-INFER-005
- Version
- 2.0.0
Definition at line 325 of file backend.cpp.
◆ generate_streaming_seq()
| GenerationResult entropic::InferenceBackend::generate_streaming_seq | ( | int | seq_id, |
| const std::vector< Message > & | messages, | ||
| const GenerationParams & | params, | ||
| std::function< void(std::string_view token)> | on_token, | ||
| std::atomic< bool > & | cancel | ||
| ) |
Streaming generation with explicit sequence ID.
Streaming generation with sequence ID.
- Parameters
-
seq_id Sequence identifier. messages Conversation history. params Generation parameters. on_token Per-token callback. cancel Cancellation flag.
- Returns
- GenerationResult with seq_id set.
- Version
- 1.9.13
Requires ACTIVE.
- Parameters
-
seq_id Sequence identifier. messages Conversation history. params Generation parameters. on_token Per-token callback. cancel Cancellation flag.
- Returns
- GenerationResult with seq_id set. @dg_internal
- Version
- 2.0.0
Definition at line 730 of file backend.cpp.
◆ info()
| BackendInfo entropic::InferenceBackend::info | ( | ) | const |
Get backend metadata.
- Returns
- BackendInfo populated from model metadata after load(). Returns default (empty) info with name only if COLD.
Base class returns a default-constructed BackendInfo with name from do_backend_name(). Subclasses override do_info() to populate architecture, quantization, memory usage, etc.
- Version
- 1.9.13
Delegates to do_info().
- Returns
- BackendInfo with at least name populated; the remaining fields come from model metadata read after load. @req REQ-INFER-024
- Version
- 1.9.13
Definition at line 610 of file backend.cpp.
◆ is_active()
|
inline |
◆ is_loaded()
|
inline |
◆ load()
| bool entropic::InferenceBackend::load | ( | const ModelConfig & | config | ) |
Load model into CPU RAM (COLD → WARM).
- Parameters
-
config Model configuration (path, context length, GPU layers, etc.).
- Returns
- true on success.
- Version
- 1.8.2
Acquires transition_mutex_. No-op if already WARM/ACTIVE.
- Parameters
-
config Validated model config.
- Returns
- true on success, false on failure. @dg_internal
- Version
- 2.0.0
Definition at line 54 of file backend.cpp.
◆ load_and_activate()
| bool entropic::InferenceBackend::load_and_activate | ( | const ModelConfig & | config | ) |
Bring a model to ACTIVE in as few file reads as possible.
Reach ACTIVE in as few whole-file reads as possible (gh#148).
From COLD this is ONE whole-file read, straight into the residency the config asks for (gh#148). It used to be load() then activate(): the first read placed every layer on the CPU with n_gpu_layers = 0, and the second immediately threw that model away and read the whole file again with the configured split. One cold activation, two whole-file reads of a file that can be 13 GB.
From WARM it promotes, which IS still a reload — llama.cpp ties offloading to the model load (design decision #19), so a WARM model cannot re-place its layers without being read again. That path is what keep_warm buys and is deliberately unchanged.
- Parameters
-
config Model configuration (path, context length, gpu_layers).
- Returns
- true when the backend is ACTIVE afterwards. @req REQ-INFER-002
- Version
- 2.13.0
From COLD: ONE read, straight into the residency config asks for. Before v2.13.0 this was load() + activate(), which read the whole file with n_gpu_layers = 0, discarded that model, and read the whole file again with the configured split — two reads of a file that can be 13 GB, for one cold activation.
From WARM: promotion, which IS still a reload (design decision #19 — llama.cpp ties offloading to the model load). That is the path keep_warm buys and it is deliberately unchanged.
Holds transition_mutex_ across the whole decision, so the state cannot change between choosing a path and taking it.
- Parameters
-
config Model config.
- Returns
- true when ACTIVE afterwards. @dg_internal @req REQ-INFER-002
- Version
- 2.13.0
Definition at line 200 of file backend.cpp.
◆ promote_to_active()
|
protected |
WARM → ACTIVE promotion.
WARM → ACTIVE promotion, with the transition mutex already held.
CALLER MUST HOLD transition_mutex_.
Extracted from activate() (gh#148) so load_and_activate can pick between the one-read cold path and this promotion under a SINGLE acquisition of the non-recursive transition mutex.
- Returns
- true when the backend is ACTIVE afterwards; false when it was neither WARM nor ACTIVE, or the activation failed. @dg_internal @req REQ-INFER-002
- Version
- 2.13.0
gh#148 split this out of activate() so load_and_activate can choose between the one-read cold path and this promotion under a single acquisition of the non-recursive transition mutex.
- Returns
- true when ACTIVE afterwards. @dg_internal @req REQ-INFER-002
- Version
- 2.13.0
Definition at line 105 of file backend.cpp.
◆ restore_state()
| bool entropic::InferenceBackend::restore_state | ( | int | seq_id, |
| const std::vector< uint8_t > & | buffer | ||
| ) |
Restore model state from buffer.
Restore model state.
- Parameters
-
seq_id Sequence identifier to restore into. buffer Previously saved state buffer.
- Returns
- true on success. false if incompatible or unsupported.
- Version
- 1.9.13
Requires ACTIVE.
- Parameters
-
seq_id Sequence identifier. buffer Previously saved state.
- Returns
- true on success; false when the backend is not ACTIVE or does not support the operation. @req REQ-INFER-024
- Version
- 2.0.0
Definition at line 650 of file backend.cpp.
◆ save_state()
Save model state to buffer.
Save model state.
- Parameters
-
seq_id Sequence identifier (0 for single-sequence backends). buffer Output buffer. Caller owns the returned data.
- Returns
- true on success. false if not ACTIVE or unsupported.
For transformers: saves KV cache state for the sequence. For recurrent: saves hidden state.
- Version
- 1.9.13
Requires ACTIVE.
- Parameters
-
seq_id Sequence identifier. buffer Caller-owned output buffer.
- Returns
- true on success; false when the backend is not ACTIVE or does not support the operation. @req REQ-INFER-024
- Version
- 2.0.0
Definition at line 625 of file backend.cpp.
◆ set_hooks()
|
inlineprotected |
◆ state()
|
inline |
◆ supports()
| bool entropic::InferenceBackend::supports | ( | BackendCapability | cap | ) | const |
Query whether this backend supports a capability.
Query backend capability.
- Parameters
-
cap Capability to query.
- Returns
- true if supported.
Base class returns false for all capabilities. Subclasses override do_supports() to declare their capabilities. Lock-free — no state transitions involved.
- Version
- 1.9.13
Delegates to do_supports().
- Parameters
-
cap Capability to query.
- Returns
- true if supported; the base default declares nothing, so an unimplemented backend under-promises rather than over-promises. @req REQ-INFER-024
- Version
- 1.9.13
Definition at line 575 of file backend.cpp.
◆ tokenize_text()
|
inlinevirtual |
Tokenize text to token IDs.
- Parameters
-
text Input text.
- Returns
- Token ID vector (empty if COLD or error). @utility
- Version
- 1.10.2
Reimplemented in entropic::LlamaCppBackend.
◆ tool_call_close_marker()
|
inlinevirtual |
The tool-call CLOSE marker for the active chat format (gh#103).
Returns the string that terminates a single tool call in the model's native format (e.g. "</tool_call>"), or "" when there is no reliable marker (no tools staged / content-only format). The orchestrator appends it to GenerationParams.stop for tiers in "sequential" tool_call_mode so the decode loop halts at the FIRST closed tool call (one tool/turn). Default "" → no stop injected (batch behavior). Backends that own a native tool-call format override this. (gh#103)
- Returns
- Close marker, or empty if none applies. @utility
- Version
- 2.8.2
Reimplemented in entropic::LlamaCppBackend.
◆ unload()
| void entropic::InferenceBackend::unload | ( | ) |
Full unload (→ COLD).
Releases all RAM + VRAM.
- Version
- 1.8.2
Idempotent.
The base half of teardown: fires ON_MODEL_UNLOAD, delegates the resource release to do_unload(), and lands the state machine in COLD. Safe to call on a backend whose load failed, and safe to call twice.
@req REQ-INFER-002
- Version
- 1.9.1
Definition at line 159 of file backend.cpp.
Member Data Documentation
◆ last_error_
|
protected |
◆ state_
|
protected |
State transition slot accessible to subclasses for test-only injection.
Pre-v2.3.10 this lived in the private section, blocking LlamaCppBackend::inject_tokenizer_for_test from flipping the backend into WARM without a real model. Production code path (load/activate/etc) still owns the normal transitions; this opens just a side door for mocks.
- Version
- 2.3.10
The documentation for this class was generated from the following files:
- entropic/inference/backend.h
- inference/backend.cpp
