gh#144: derive a tier's KV geometry from max_sessions, purely. More...
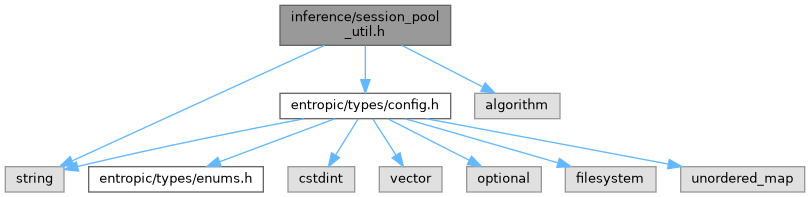
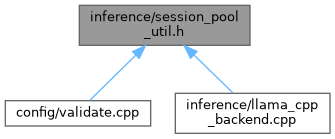
Go to the source code of this file.
Classes | |
| struct | entropic::PoolGeometry |
| Context geometry derived from a tier's session-pool request. More... | |
Namespaces | |
| namespace | entropic |
| Activate model on GPU (WARM → ACTIVE). | |
Functions | |
| PoolGeometry | entropic::derive_pool_geometry (const ModelConfig &cfg) |
| Derive the context geometry a tier's config implies. | |
| std::string | entropic::session_pool_conflict_reason (const ModelConfig &cfg) |
| Why this tier's session-pool request cannot be honoured. | |
Detailed Description
gh#144: derive a tier's KV geometry from max_sessions, purely.
- Why this is a pure header
- The same reason
warm_keep_util.his: the decision is a handful of integer rules that decide whether a deployment fits on the card, and it must be assertable by a CPU unit test with no model, no GPU and no llama.cpp context.build_cparamsapplies the result; it does not decide it.
- The geometry, and why non-unified
- Verified against the vendored llama.cpp: total KV memory is
n_ctxworth of cells EITHER WAY (llama-kv-cache.cpp:98,247— the tensors are(n_embd_k_gqa, kv_size, n_stream)withn_stream = unified ? 1 : n_seq_max, andllama-context.cpp:229-243setsn_ctx_seq = n_ctxwhen unified,n_ctx / n_seq_maxwhen not). So unified is NOT cheaper. The difference is one shared pool versusn_seq_maxPRIVATE guaranteed streams.
Non-unified is chosen on fail-fast grounds, not memory. Under unified a session that grows toward the full window starves the others and llama_decode returns "could not find a KV slot" — a runtime failure with a poor diagnostic and no attribution to a session. Non-unified converts that into a per-session context overflow the existing compaction path already handles against context_length.
It also keeps n_ctx_seq inside the model's trained context. For three 32768 sessions, unified would report n_ctx_seq = 98304 and trip llama.cpp's training-overflow warning (llama-context.cpp:263); non-unified reports 32768 per stream.
An operator who genuinely wants the cheap shared variant can still have it by setting max_sessions: 3, context_length: 12288 — the pool then costs exactly today's allocation.
- Version
- 2.12.0
Definition in file session_pool_util.h.
